
About Me
Qixiang Chen is a second-year Ph.D. student in the Department of Data Science and AI at Monash University, supervised by Prof. Jianfei Cai and Dr. Jingwen Ye. Before that, he received his Bachelor of Advanced Computing (Honours), majoring in Computer Vision and Machine Learning, from the Australian National University.
His research interests include multimodal learning, 3D spatial reasoning, vision-language models, and video understanding.
Education
Ph.D. in Information Technology, Monash University, Aug 2025 – Present
Bachelor of Advanced Computing (Honours), The Australian National University, Jul 2022 – Jul 2025
Publications
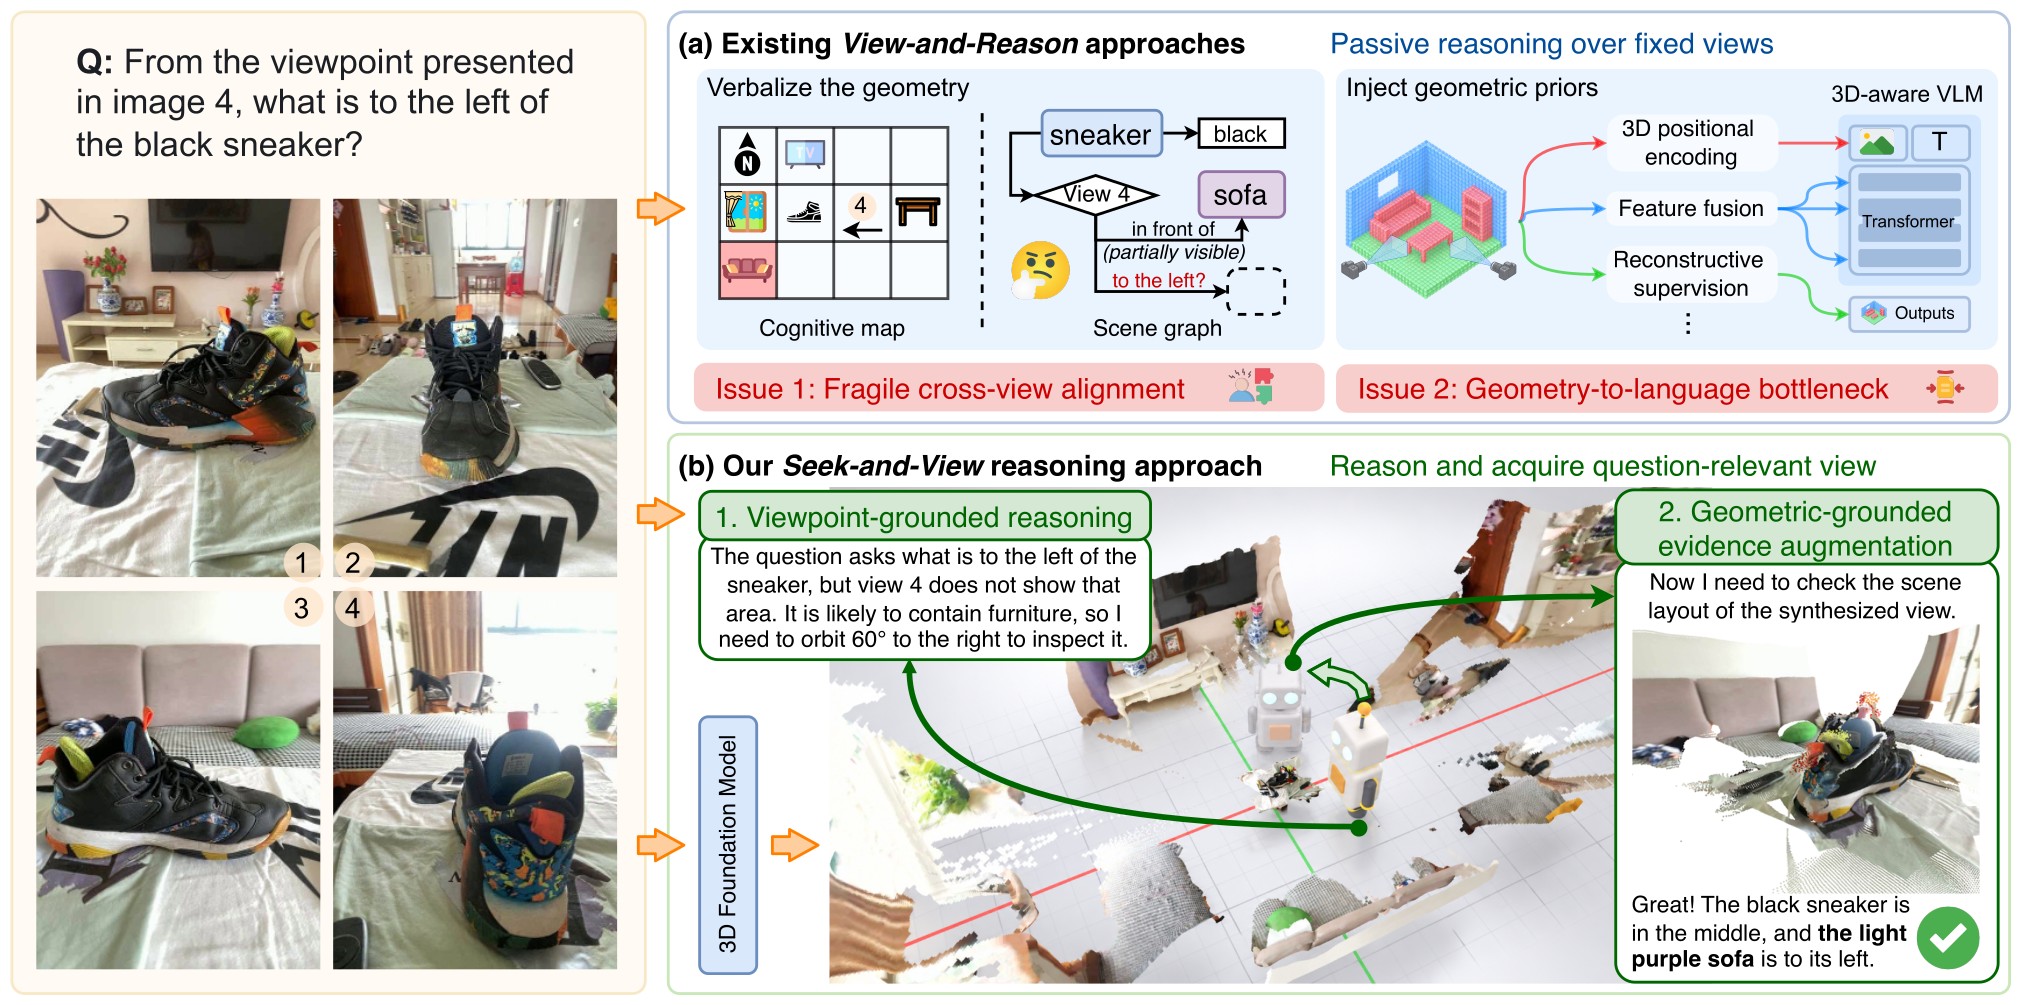
Seek-and-View Reasoning for Multi-View Spatial Understanding
arXiv preprint, 2026
A Seek-and-View reasoning paradigm that seeks a question-relevant view to make the spatial evidence directly observable, realized by Vantage, a training-free and model-agnostic framework coupling VLM reasoning with a 3D foundation model.
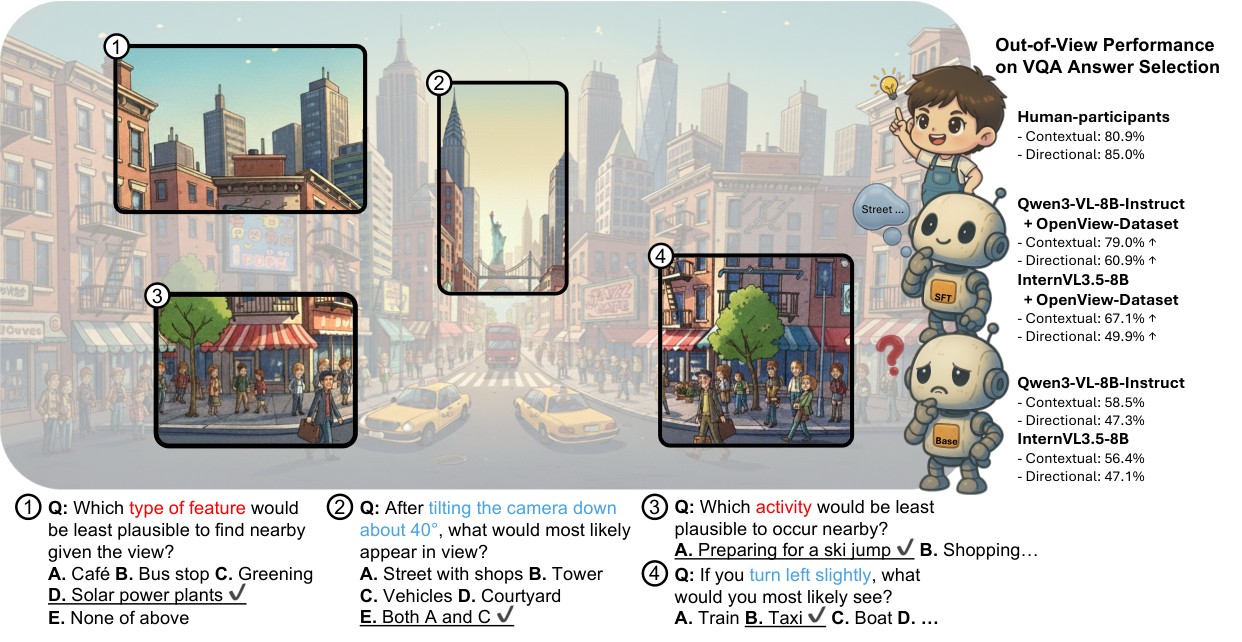
OpenView: Empowering MLLMs with Out-of-view VQA
The 40th Conference on Neural Information Processing Systems (NeurIPS 2026), Evaluations & Datasets Track
Out-of-view (OOV) VQA asks MLLMs to reason about objects, activities, and scenes beyond the visible frame of an image. We build a VQA synthesis pipeline to construct OpenView-Dataset, and a human-annotated OpenView-Bench for evaluation.
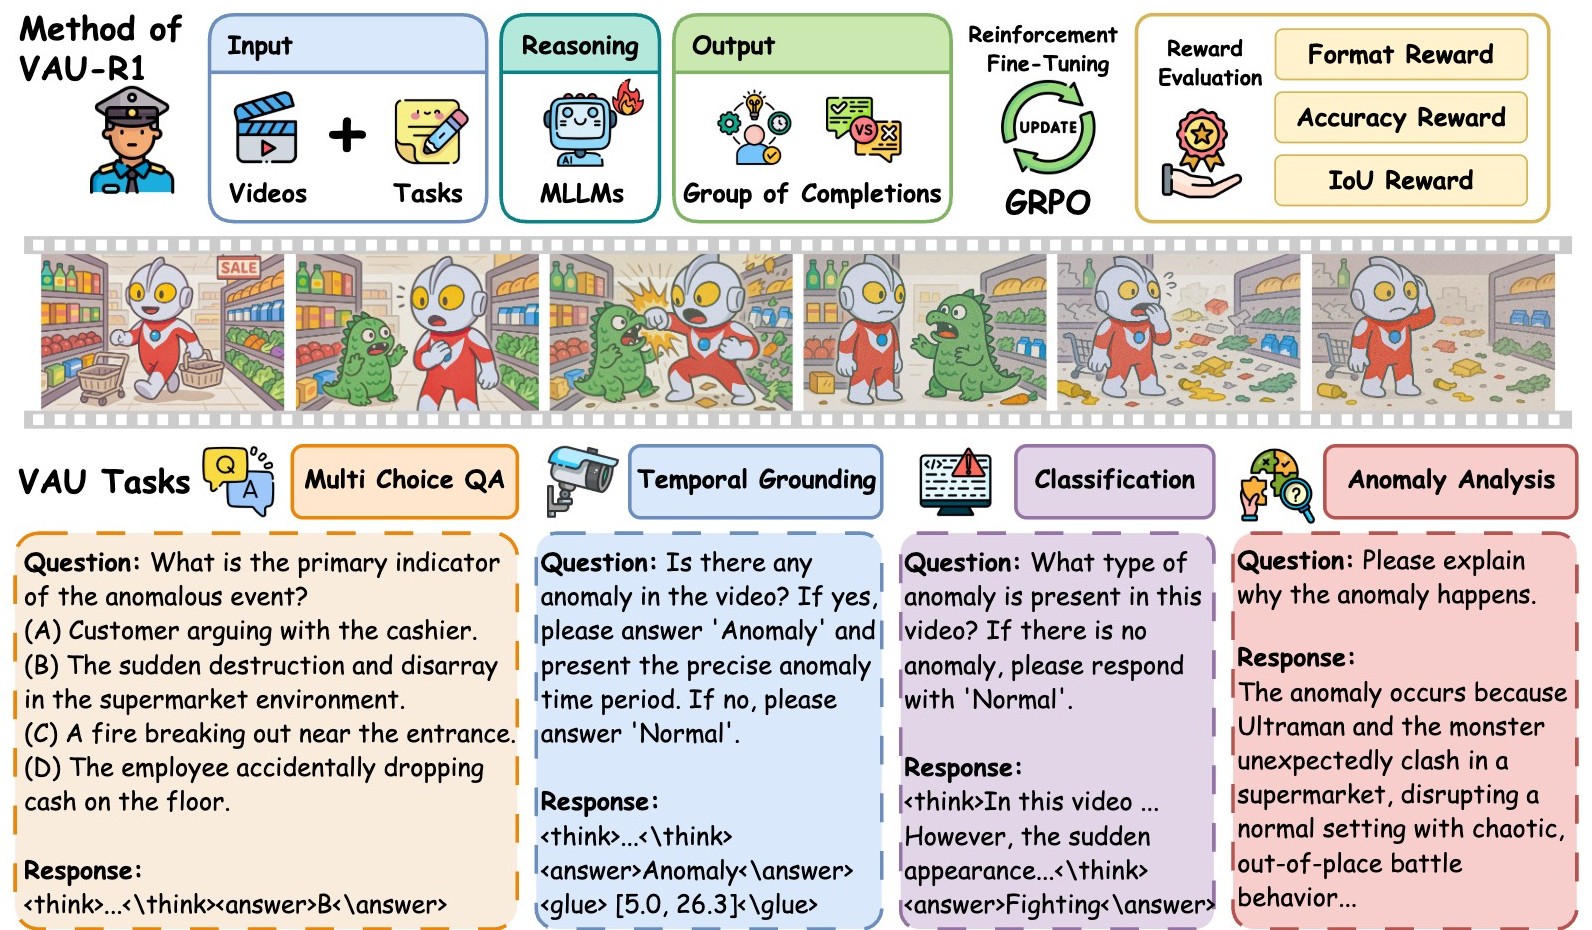
VAU-R1: Advancing Video Anomaly Understanding via Reinforcement Fine-Tuning
arXiv preprint, 2025
A reinforcement fine-tuning framework that strengthens MLLM reasoning for video anomaly understanding, together with VAU-Bench, the first large-scale Chain-of-Thought benchmark for anomaly reasoning.
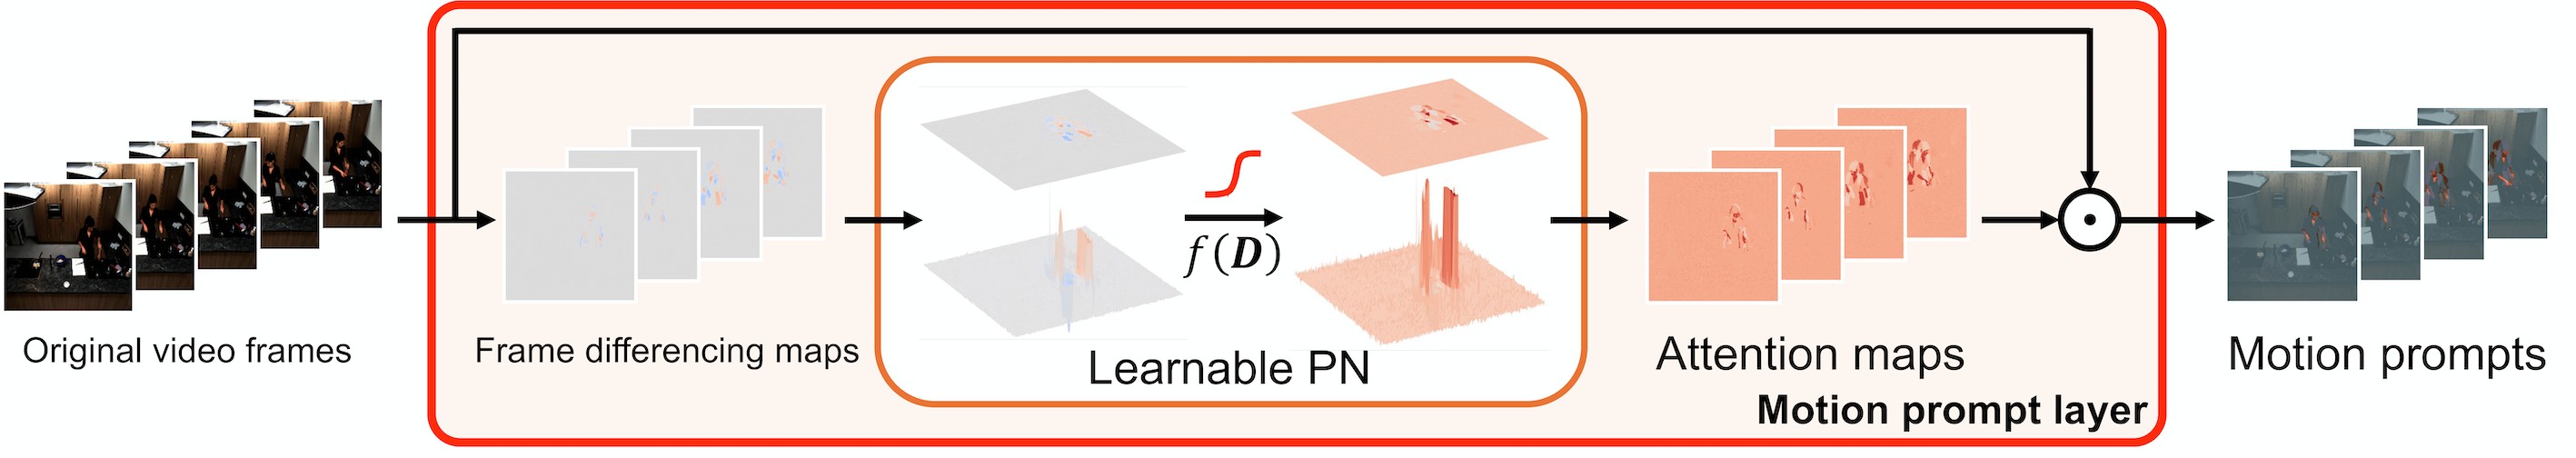
Motion meets Attention: Video Motion Prompts
The 16th Asian Conference on Machine Learning (ACML 2024)
Long Presentation (5.67%)
Long Presentation (5.67%)
A plug-and-play motion prompt layer that turns frame differencing maps into attention maps, so video models focus on the motion that matters for fine-grained action recognition.
Projects
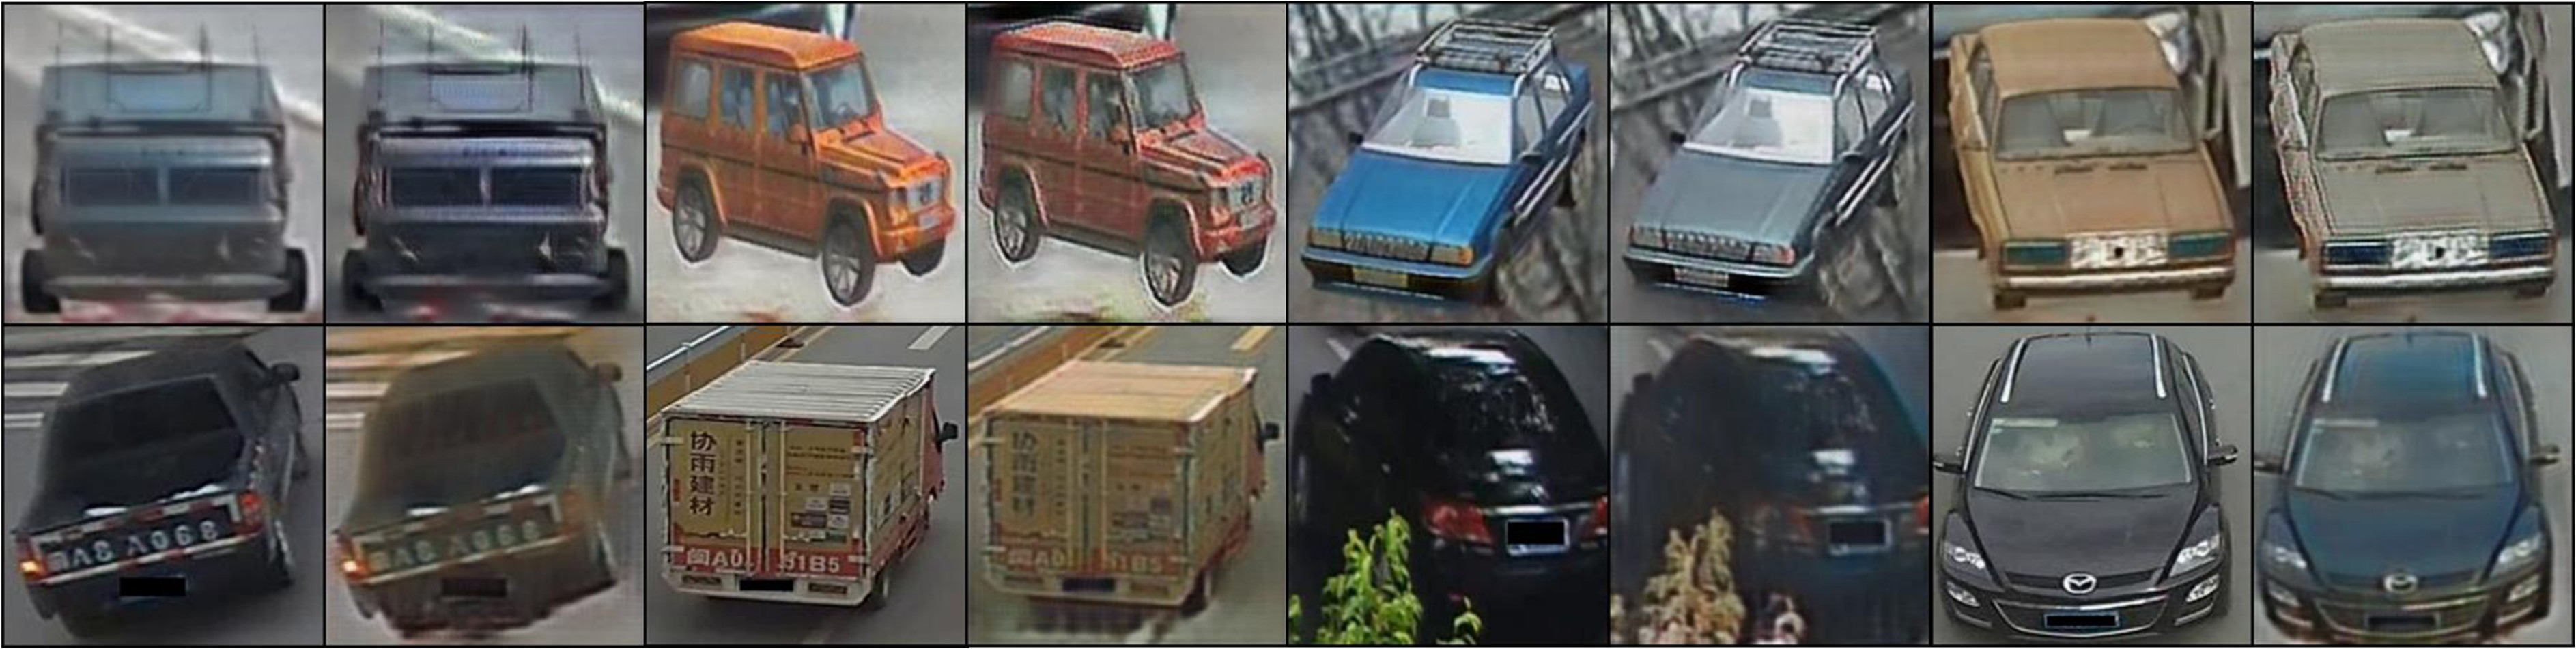
Vehicle Image Translation: Adapting Synthetic Styles to Real-World Scenarios
Course Project, COMP4660 Neural Networks, Deep Learning and Bio-inspired Computing, ANU, 2023
CycleGAN-based translation of synthetic Vehicle-X images into the style of the real-world VeRi dataset, improving domain adaptation for vehicle recognition.